We provide dedicated data engineers who handle the full data flow: extracting data from your sources, cleaning and transforming it, and structuring it in a warehouse that is easy to query and trust. From ETL pipelines to dimensional models and Power BI reporting, you get reliable data your team can actually rely on.

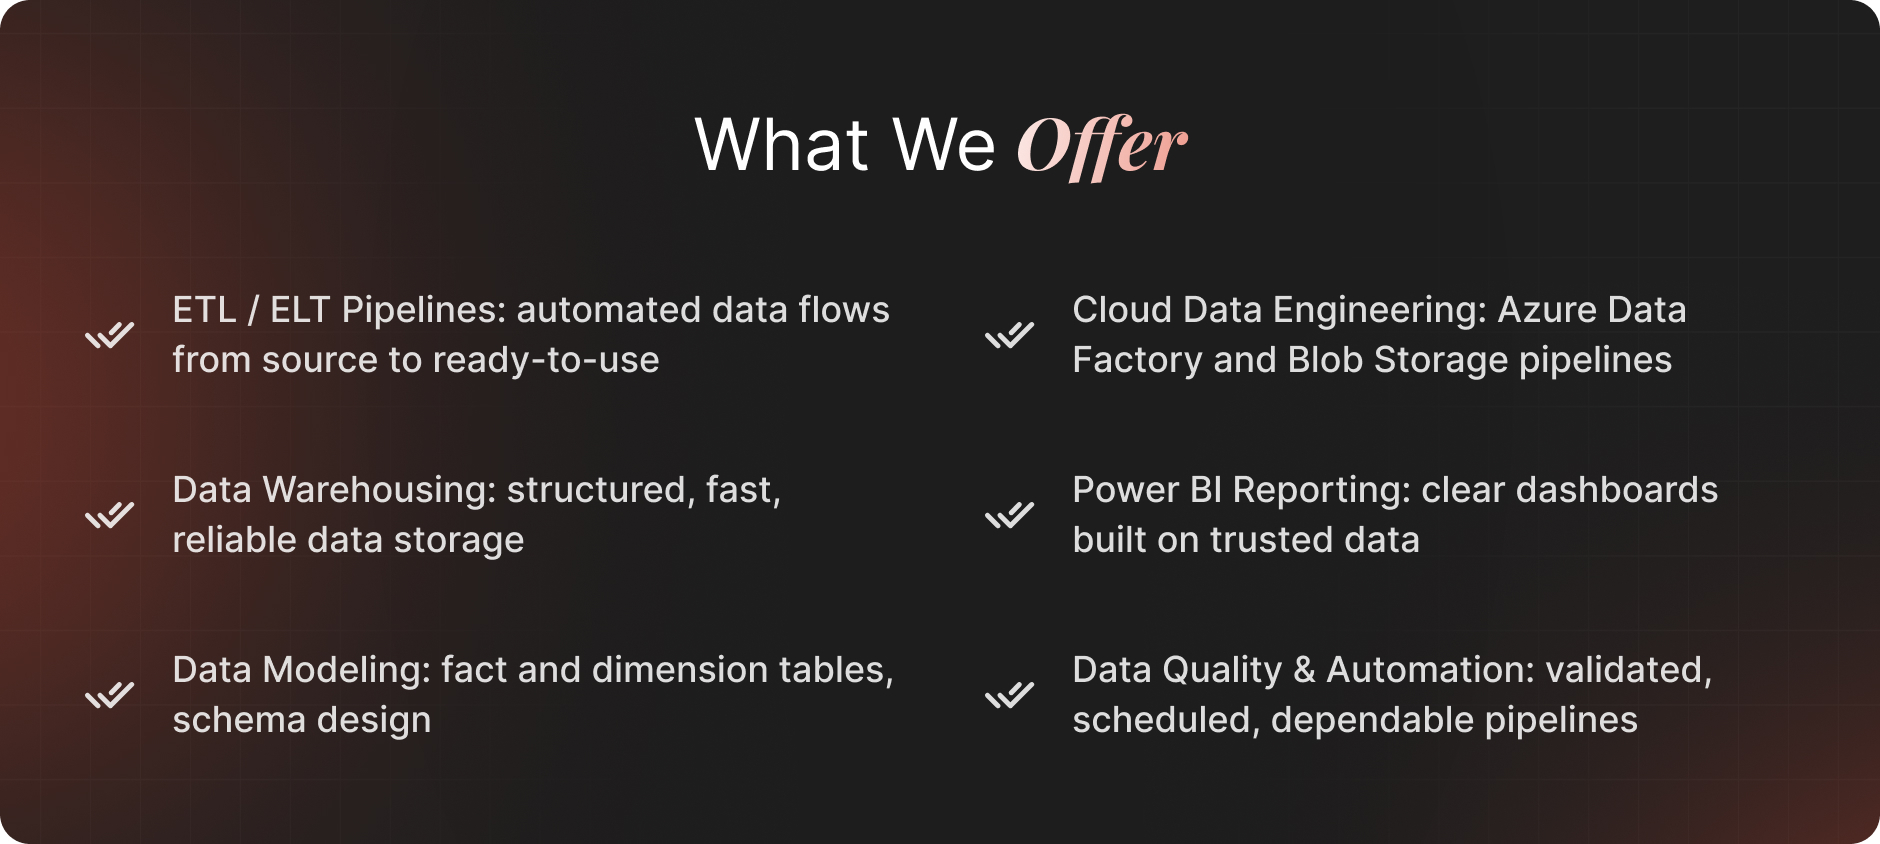
Common use cases include building automated ETL pipelines with Bronze, Silver, and Gold layers, designing data warehouses with fact and dimension tables, updating schemas to support new KPIs, and building Power BI dashboards on clean data. It also covers centralizing data into the cloud and replacing manual data work with reliable automation.
Our data engineers work with Snowflake, SQL, Python, Pentaho, and Azure Data Factory, with Azure Blob Storage for scalable storage and Medallion architecture for clean, layered data. We handle dimensional modeling, schema design and evolution, stored procedures, and indexing, and connect the results to Power BI, with Git and CI/CD for reliable delivery.
Share your data sources (systems, portals, files, or APIs) and what you want to report on or achieve. Provide access or sample data, any cleaning or KPI rules, and where the final data should live. Example reports or metrics help us design the right pipelines and models.


